Everyone seems to be building a Retrieval-Augmented Generation (RAG) system. It makes sense. The ability to ground a Large Language Model (LLM) in your own private data, from internal wikis to customer support tickets, unlocks powerful and specific business applications. Getting a proof-of-concept running in a notebook is straightforward, often taking just a few hours with a library like LangChain or LlamaIndex.
But taking that prototype and turning it into a production-ready service is a different challenge entirely. A production system must be reliable, scalable, observable, and maintainable. It needs to handle messy, real-world data and user queries with grace. This isn't just a machine learning problem; it's a software engineering one.
Moving from a simple script to a robust RAG system requires a shift in thinking. It involves building a series of interconnected, production-grade pipelines. Here’s a detailed look at the architecture and the practical steps required to build one.
The Anatomy of a Production RAG System
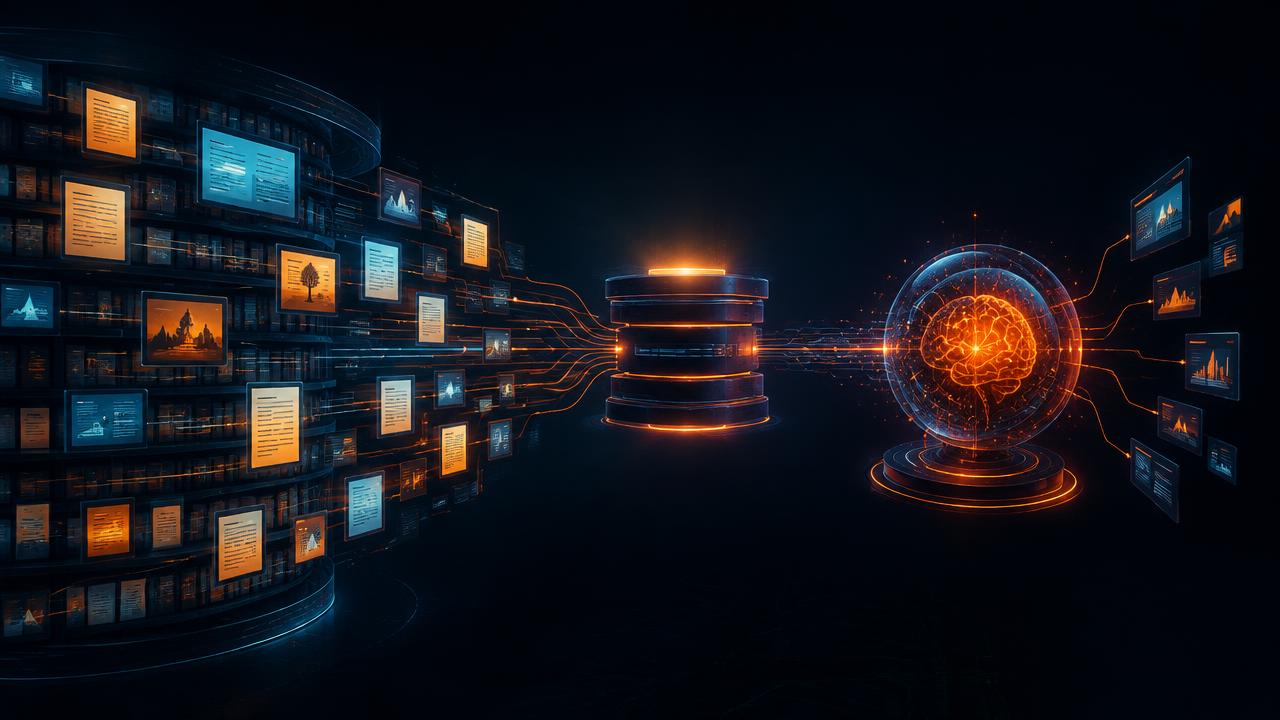
A production RAG architecture can be broken down into four key stages: Data Ingestion and Processing, Embedding and Indexing, Retrieval and Reranking, and finally, Generation. Each stage has its own set of engineering considerations.
![A diagram showing the flow of a production RAG system would be useful here, but I will describe it in text]
- Ingestion: Raw data from various sources is collected.
- Processing: Data is cleaned, extracted, and chunked.
- Indexing: Chunks are converted into vectors and stored in a vector database.
- Retrieval: A user query is used to find relevant chunks from the database.
- Reranking: The retrieved chunks are re-ordered for maximum relevance.
- Generation: The query and the top chunks are passed to an LLM to generate a final answer.
Let's break down what it takes to build each component for production.
Step 1: Building a Resilient Data Ingestion Pipeline
Your RAG system is only as good as the data it can access. In a business context, this data is rarely a clean set of text files. It's spread across APIs, databases, and third-party platforms.
Data Sources and Connectors
Production data lives everywhere. It could be in Confluence, Jira, Slack, Salesforce, or a collection of PDFs in an S3 bucket. Your first task is to build reliable connectors to these sources.
- For APIs: Use robust client libraries with built-in retry logic (like
tenacityfor Python) to handle transient network errors. - For Databases: Your pipeline should connect securely, perhaps through a read-only replica to avoid impacting production database performance.
- For Unstructured Files: Tools like
Unstructured.ioare excellent for extracting clean text and metadata from complex file types like PDFs, HTML, and PowerPoint presentations.
The goal is an automated, resilient pipeline, not a manual script you have to run periodically. This pipeline should be triggerable, either on a schedule (e.g., nightly) or via webhooks when data is updated at the source.
Chunking Strategies: Beyond Fixed Sizes
Once you have the text, you must split it into manageable pieces, or "chunks." A simple fixed-size chunker (e.g., 1000 characters with 200 character overlap) is a common starting point, but it's often suboptimal. It can awkwardly split a sentence or separate a question from its answer.
Production systems benefit from more sophisticated strategies:
- Semantic Chunking: This method splits text based on semantic similarity. It uses an embedding model to decide where the topic of the text shifts, creating more contextually coherent chunks.
- Agentic Chunking: A newer technique where an LLM agent actively decides how to break down a document. For example, it might summarize an entire section and then create smaller, more detailed chunks for subsections, creating a hierarchical structure.
Crucially, you must attach metadata to every chunk. Store the source document URL, creation date, title, and any other relevant identifiers. This is not optional. Without it, you can't filter results (e.g., "only search documents created in the last year") or provide citations, which is a core requirement for user trust.
Step 2: The Embedding and Indexing Layer
This is where your processed data becomes searchable. It involves converting your text chunks into numerical representations (embeddings) and storing them in a specialized database for fast retrieval.
Choosing Your Embedding Model
The model you use to create vectors has a direct impact on retrieval quality. While OpenAI’s text-embedding-3-small is a popular and cost-effective choice, you have other options.
- Proprietary Models: Cohere’s
embed-english-v3.0is a strong performer, especially for retrieval tasks. - Open Source Models: Models from Hugging Face’s MTEB (Massive Text Embedding Benchmark) leaderboard, like
bge-large-en-v1.5, can offer competitive performance and give you more control, though you'll need to host them yourself.
Your choice involves a trade-off between cost, performance, and operational overhead. Run experiments with a few models on a representative sample of your data to see which one performs best for your specific domain.
Selecting a Vector Database
Your vector database is the heart of the retrieval system. It needs to be fast, scalable, and reliable.
- Managed Services (Pinecone, Zilliz Cloud): These are the easiest to get started with. They handle scaling, backups, and maintenance for you. Pinecone is known for its performance and ease of use, making it a strong choice for teams that want to move fast.
- Open Source (Weaviate, Qdrant, Chroma): These offer more control and can be self-hosted, which might be a requirement for data privacy or cost management reasons. Weaviate, for instance, has strong support for hybrid search and flexible data models. Chroma is developer-friendly and great for smaller projects.
- Database Extensions (pgvector for Postgres): If your team is already heavily invested in PostgreSQL, using an extension like
pgvectorcan be a good option. It keeps your stack simpler, though dedicated vector databases often provide better performance at very large scales.
A key feature to look for in production is support for hybrid search. This combines traditional keyword search (like BM25) with modern vector search. Why? Vector search is great for semantic meaning, but it can struggle with specific acronyms, product codes, or names. Keyword search excels at these. Combining them provides the best of both worlds and significantly improves retrieval quality.
Step 3: Advanced Retrieval and Reranking
Simply fetching the top five most similar chunks from your vector database is often not enough for production-grade answers. The noise from marginally relevant documents can confuse the LLM and lead to weaker, more generic responses.
The Two-Stage Retrieval Process
A better approach is a two-stage process: retrieve, then rerank.
- Retrieval: In the first stage, you cast a wide net. Instead of fetching just the top 3 or 5 chunks (
k=5), you retrieve a larger number, maybe the top 20 or 50 (k=50). This increases the probability that the "perfect" answer is somewhere in the retrieved set. - Reranking: In the second stage, you use a more sophisticated, computationally expensive model to re-score this smaller set of 50 documents based on their specific relevance to the user's query. A reranker, like Cohere’s Rerank API or an open-source cross-encoder model, is designed for this. It looks at the query and each document together, leading to a much more accurate relevance score than the vector database lookup alone.
After reranking, you take the new top 3 or 5 chunks and pass them to the LLM. This process dramatically improves the signal-to-noise ratio of your context, directly leading to better, more factual answers.
Step 4: Orchestration, Generation, and Monitoring
This is where all the pieces come together to produce an answer for the user. It’s also where you build the tooling to ensure the system stays healthy.
Orchestration and Generation
You need a service that executes the RAG pipeline: takes a user query, performs retrieval and reranking, constructs a prompt with the context, and calls the LLM.
- Orchestration Frameworks: LangChain and LlamaIndex are popular choices for orchestrating these steps. They provide abstractions that can speed up development. However, for a high-performance, production-focused system, some teams opt to write their own orchestration logic using basic Python libraries. This avoids complex abstractions, making the code more transparent and easier to debug, optimize, and maintain.
- Prompt Engineering: Production prompts are rarely just
f"Context: {context}\n\nQuestion: {query}\n\nAnswer:". They are carefully engineered templates that include system instructions, examples of desired output format (e.g., Markdown, JSON), and placeholders for retrieved context. - Choosing an LLM: Your choice of generator model (e.g., OpenAI’s
gpt-4o, Anthropic’sclaude-3-opus, or an open-source model likellama-3-70b) depends on your budget, latency requirements, and the complexity of the task. For many internal Q&A tasks, a faster and cheaper model likeclaude-3-sonnetis often sufficient.
Evaluation, Logging, and Monitoring
You cannot run a production AI system blind. You need robust evaluation and monitoring from day one.
Evaluation Frameworks: Before deploying, you need to measure the quality of your system. Create a "golden set" of question-answer pairs and use a framework like RAGAs or TruLens to evaluate performance. These tools measure key metrics:
- Faithfulness: Does the answer contradict the provided context?
- Answer Relevancy: Is the answer relevant to the user's query?
- Context Precision: Are the retrieved chunks actually relevant to the query?
- Context Recall: Were all necessary chunks retrieved?
Observability and Logging: Instrument your RAG pipeline to log everything. Track the incoming query, the retrieved chunks, the reranked chunks, the final prompt, and the generated response. Tools like Langfuse, Arize AI, or Weights & Biases are built for this "LLM-ops" monitoring. They provide traces that let you visualize the entire flow of a request, which is invaluable for debugging a bad answer.
Performance and Cost Monitoring: Track core operational metrics in a dashboarding tool like Datadog or Grafana. Monitor API error rates, latency for each component (retrieval, reranking, generation), and, critically, the cost per query. Without this, your costs can spiral out of control.
Maintaining the System Over Time
A production RAG system is a living product, not a one-off project. It requires ongoing maintenance. Your biggest challenge will be ensuring data freshness. How do you keep the vector index synchronized with your source data?
Your ingestion pipeline needs to handle updates. For a source like Confluence, you could use webhooks to trigger a re-indexing of a specific page the moment it's updated. For other systems, a nightly batch job that checks for modified documents might be more appropriate. Devising this update strategy is a critical, non-trivial piece of engineering.
Furthermore, you need a feedback loop. When a user gives a "thumbs down" to an answer, that signal should be captured. A human reviewer can then analyze the trace for that query. Was the retrieval poor? Was the document content out of date? Was the LLM hallucinatory? This feedback is the raw material for continuous improvement.
Building a production-ready RAG system is about applying software engineering discipline to an AI problem. It’s about moving beyond the notebook and thinking in terms of data pipelines, observability, test-driven development, and reliability. The tools are rapidly evolving, but the core principles of building robust, maintainable systems remain the most important asset you can have.
And if you need any help creating a RAG - let us know!